NO.33 You are currently asked to work on building a data pipeline, you have noticed that you are currently working on a very large scale ETL many data dependencies, which of the following tools can be used to address this problem?
Explanation
The answer is, DELTA LIVE TABLES
DLT simplifies data dependencies by building DAG-based joins between live tables. Here is a view of how the dag looks with data dependencies without additional meta data,
1.create or replace live view customers
2.select * from customers;
3.
4.create or replace live view sales_orders_raw
5.select * from sales_orders;
6.
7.create or replace live view sales_orders_cleaned
8.as
9.select sales.* from
10.live.sales_orders_raw s
11. join live.customers c
12.on c.customer_id = s.customer_id
13.where c.city = ‘LA’;
14.
15.create or replace live table sales_orders_in_la
16.selects from sales_orders_cleaned;
Above code creates below dag
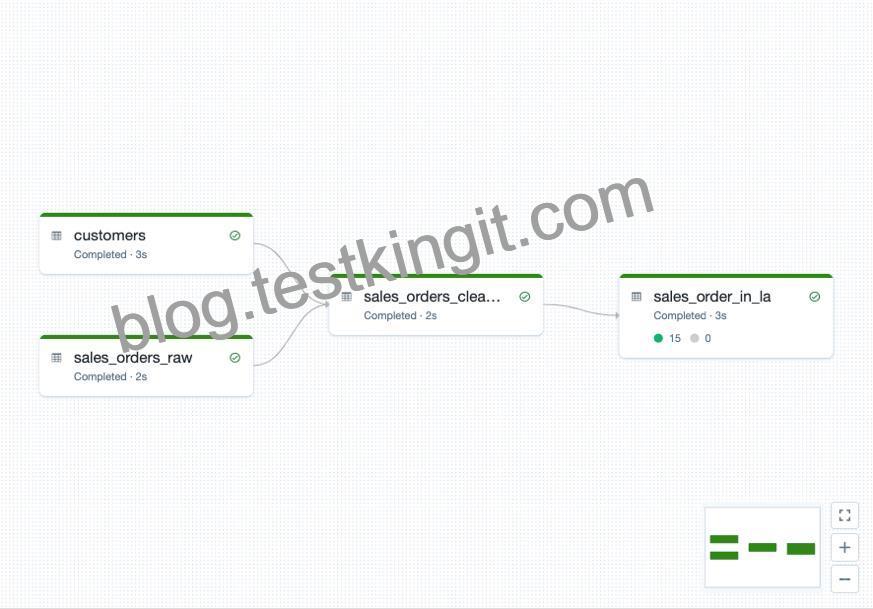
Documentation on DELTA LIVE TABLES,
https://databricks.com/product/delta-live-tables
https://databricks.com/blog/2022/04/05/announcing-generally-availability-of-databricks-delta-live-tables-dlt.htm DELTA LIVE TABLES, addresses below challenges when building ETL processes
1.Complexities of large scale ETL
a.Hard to build and maintain dependencies
b.Difficult to switch between batch and stream
2.Data quality and governance
a.Difficult to monitor and enforce data quality
b.Impossible to trace data lineage
3.Difficult pipeline operations
a.Poor observability at granular data level
b.Error handling and recovery is laborious
